Loading feed…

Medium0 Hot0 comments8 min read
Your AI is begging you to start a new chat. It should just do it.
Your AI is begging you to start a new chat. It should just do it. I feel like I’m being harassed daily by my AI tools. It shows up as a gray banner or a line of help text. This conversation is …
Source: https://medium.com/@lisachinmollica/your-ai-is-begging-you-to-start-a-new-chat-it-should-just-do-it-d14ecc2e389f. 8 Sync News only summarizes and links out; content copyright belongs to the authors and original sources.
8 Sync ecosystem
One account, the whole ecosystem
Read the news here, practice coding, follow structured courses and train for IELTS on our sibling products — all connected through one 8 Sync account.
8syncdev.com
8syncdev.comThe ecosystem home: product overviews, blog and full pricing.
ExploreCourses
course.8syncdev.comLearn along a clear roadmap: videos, auto-graded quizzes, certificates and mentors who ship for a living.
View the roadmapCoding practice
coding.8syncdev.com1,000 DSA problems in Vietnamese, auto-graded across 7 languages — many FREE, right in your browser.
Practice for freeIELTS
ielts.8syncdev.comAI grading for all four IELTS skills with detailed rubric feedback.
Try it freeZUS — AI IDE
zus.8syncdev.comA 22 MB AI IDE for Vietnamese devs.
Download freemind0
mind0.8syncdev.comOrganizational memory for AI agents.
ExploreAcoLeads
home-acoleads.8syncdev.comAI that staffs your Fanpage and qualifies leads for you.
Try itRecommended for you

Medium1 Hot10 min
Stop Asking ChatGPT to Write Your Code. Ask It This Instead
Stop Asking ChatGPT to Write Your Code. Ask It This Instead Learning to code is frustrating. Nobody warns you how frustrating. You watch the tutorials. You read the docs. You follow along with every …
Daily Dose of Data Science | Avi Chawla | Substack79 Hot7 min
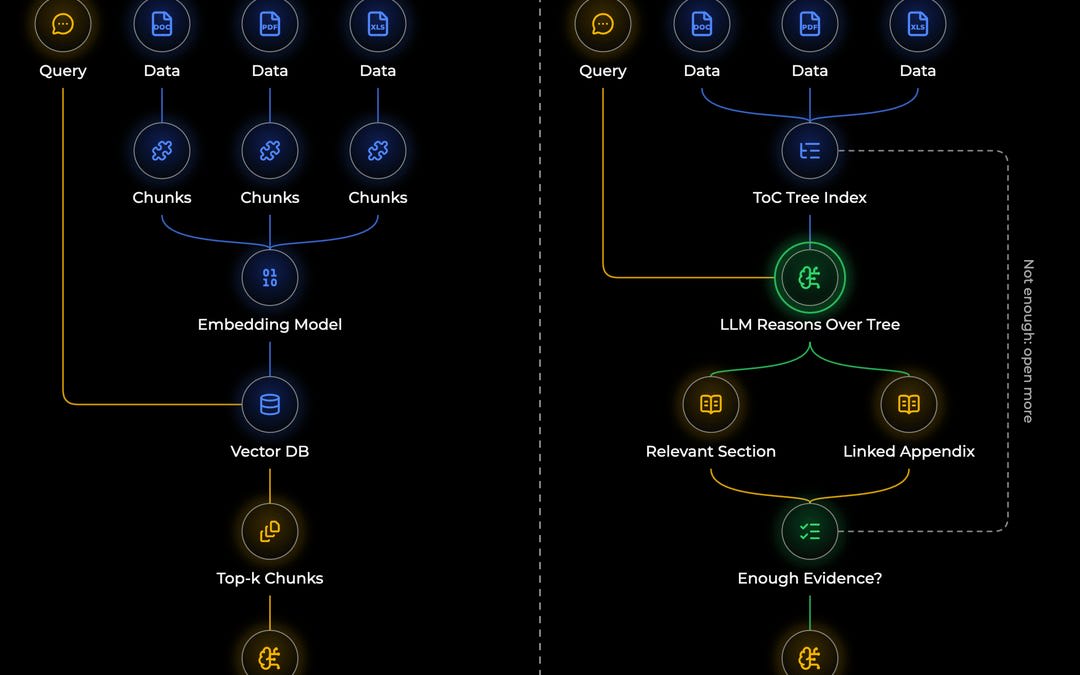
RAG vs. Vectorless RAG, clearly explained!
...explained visually (with tradeoffs in production).

DEV1 Hot12 min
I Retested My MoE Offloading Benchmarks. Some of My Conclusions Changed.
A follow-up to my original 16GB GPU experiment, this time with consistent quantization, repeated... Tagged with ai, machinelearning, llm.

Hacker News50 Hot6 minAI
Colorfigures
Colorfigures là một AI skill có khả năng tạo ra hình ảnh 3D isometric của các đồ vật hàng …
Daily Dose of Data Science | Avi Chawla | Substack17 Hot9 min
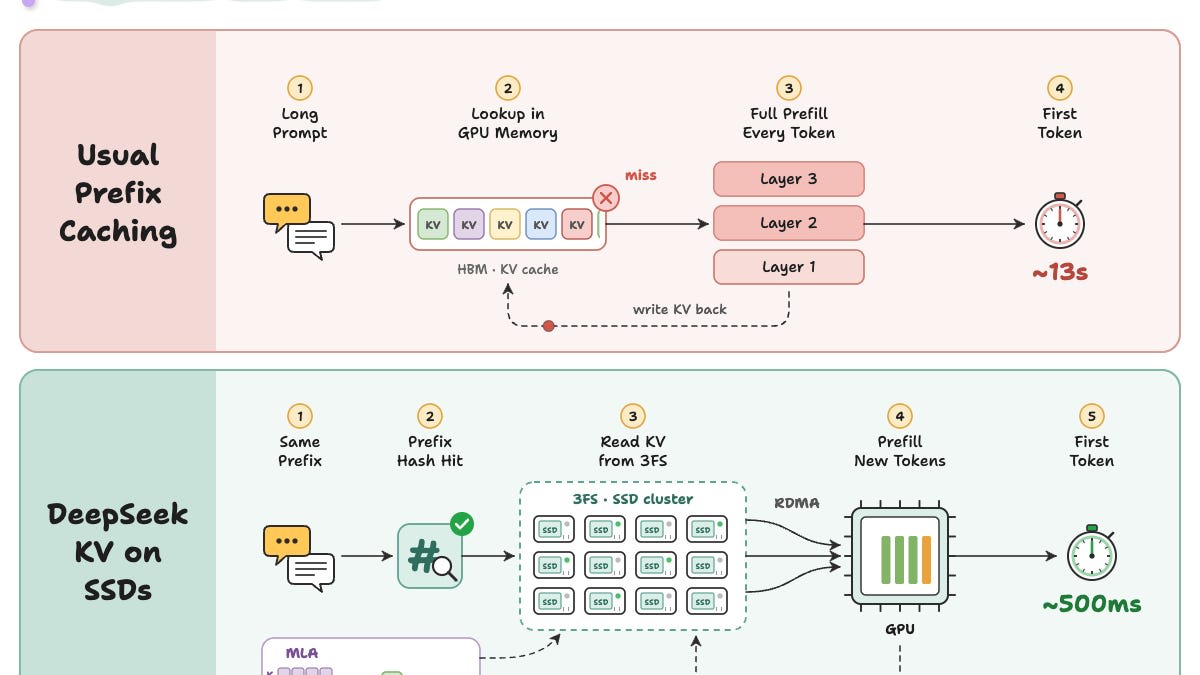
Why DeepSeek stores its KV cache on disk
DeepSeek's engineering behind 26x faster time to first token.

Dribbble25 Hot8 minAI
5 UX Patterns for Driving Patient Engagement in Healthcare App Design
Trong lĩnh vực healthcare app design, việc tăng patient engagement là thách thức lớn khi …

Daily Dose of Data Science | Avi Chawla | Substack36 Hot10 minAI
6 KV Cache Quantization Approaches
Bối cảnh về KV Cache Quantization trở nên quan trọng khi inference model lớn như GPT-3 cần xử lý hàng tỷ parameters. Nguyên nhân kỹ thuật là do KV Cache chiếm tới 40% bộ nhớ VRAM, tạo ra bottleneck đáng kể cho các inference server. Hệ quả rõ ràng là việc lượng hóa KV Cache giúp giảm 50-70% bộ nhớ sử dụng và tăng tốc inference đến 30%. Điều đáng học là 6 phương pháp lượng hóa KV Cache từ các nghiên cứu gần đây của NVIDIA và Google Research đều có trade-off giữa độ chính xác và hiệu suất, tùy thuộc vào hardware support cụ thể.
Cách tiếp cận KV Cache Quantization được minh họa trực quan giúp lập trình viên hiểu và tối ưu hiệu năng mô hình ngôn ngữ.
Daily Dose of Data Science | Avi Chawla | Substack12 Hot7 minAI
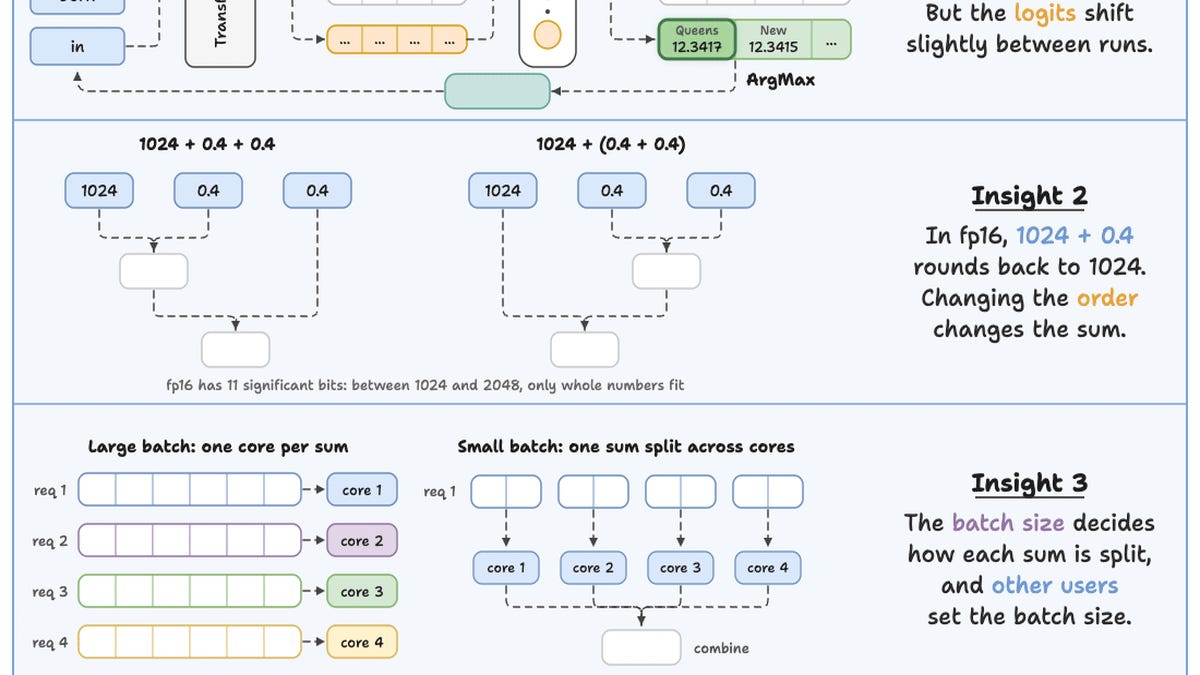
Why Temperature 0 Isn't Deterministic in LLM Inference
Trong quá trình inference của LLM, temperature 0 không hoàn toàn quyết định như nhiều người vẫn nghĩ. Nguyên nhân kỹ thuật nằm ở cách thuật toán softmax hoạt động khi temperature bằng 0, làm cho xác suất của từ với highest score tiến tới 1 nhưng không bao giờ đạt hoàn toàn 1 trong thực tế. Điều này dẫn đến kết quả có vẻ ngẫu nhiên dù xác suất đã được chuẩn hóa, gây ra sự không chắc chắn nhỏ trong kết quả output. Điều đáng học là việc hiểu behavior của temperature trong LLM không đơn giản như tưởng tượng, đòi hỏi hiểu biết sâu về cách hoạt động của softmax và quy trình sampling text generation.
Bạn nên đọc bài này để hiểu cách giải quyết một vấn đề cơ bản nhưng thường bị nhầm lẫn trong việc phân tích và tối ưu hóa mô hình ngôn ngữ lớn, giúp tránh sai lầm trong việc thiết kế và triển khai hệ thống AI.
Comments
Loading comments…