Loading feed…

XDA Developers0 Hot0 comments3 min read
Your CPU's integrated graphics can handle more than you think, and most people never turn them on
It doesn't matter how bad it is for gaming.
Source: https://www.xda-developers.com/cpus-integrated-graphics-handle-more-than-think-most-never-turn-them-on. 8 Sync News only summarizes and links out; content copyright belongs to the authors and original sources.
8 Sync ecosystem
One account, the whole ecosystem
Read the news here, practice coding, follow structured courses and train for IELTS on our sibling products — all connected through one 8 Sync account.
8syncdev.com
8syncdev.comThe ecosystem home: product overviews, blog and full pricing.
ExploreCourses
course.8syncdev.comLearn along a clear roadmap: videos, auto-graded quizzes, certificates and mentors who ship for a living.
View the roadmapCoding practice
coding.8syncdev.com1,000 DSA problems in Vietnamese, auto-graded across 7 languages — many FREE, right in your browser.
Practice for freeIELTS
ielts.8syncdev.comAI grading for all four IELTS skills with detailed rubric feedback.
Try it freeZUS — AI IDE
zus.8syncdev.comA 22 MB AI IDE for Vietnamese devs.
Download freemind0
mind0.8syncdev.comOrganizational memory for AI agents.
ExploreAcoLeads
home-acoleads.8syncdev.comAI that staffs your Fanpage and qualifies leads for you.
Try itRecommended for you

Hacker News1 Hot3 min
The $8 Linux Computer (2022)
An $8 Ox64 RISC-V single-board computer can run full Linux, not a stripped-down MMU-less kernel. It has three different RISC-V cores, but ethernet, wifi and SD card don't work yet. Flashing it is painful: it must be programmed over UART, not USB, and DevCube crashes on Wayland so you need Xorg. A CH340G USB-UART dongle failed the handshake, so the author used an RP2040 (Adafruit KB2040) running picoprobe as a serial bridge, then had to modify bflb-mcu-tool's uart interface file to strip DTR/RTS handling before it would flash the M0 core.

Noted1 Hot5 min
Someone Built a 4K Camera With a Raspberry Pi 5
A DIY camera built around a Raspberry Pi 5 features a custom enclosure, interchangeable lenses, open-source software, and 4K support.

XDA Developers125 Hot4 minAI
I changed one llama.cpp flag, and my 8GB laptop GPU now runs a 35B model faster than I can read
Một lập trình viên đã tìm ra cách chạy model Llama 35B trên laptop GPU chỉ 8GB VRAM với tốc độ đáng kinh ngạc. Nguyên nhân kỹ thuật nằm ở việc chỉnh sửa cờ n_gpu_layers trong llama.cpp, cho phép tận dụng hiệu quả bộ nhớ VRAM thay vì để nó trở thành điểm nghẽn. Hệ quả là model 35B parameters chạy nhanh đến mức người dùng không kịp theo dõi, vượt xa các kỳ vọng ban đầu về giới hạn phần cứng. Điều đáng học hỏi là đôi khi vấn đề không nằm ở cấu hình phần cứng mà ở cách tối ưu hóa phần mềm để khai thác tiềm năng thực sự của hardware.
Bài viết tiết lộ cách tối ưu hóa một cờ trong llama.cpp để chạy mô hình 35B trên GPU 8GB nhanh hơn tốc độ đọc của bạn.

Hacker News1 Hot6 min
Nvidia Kubernetes Engine (NVKE)
NVIDIA Kubernetes Engine (NVKE). A management plane for GPU Kubernetes on bare metal. - dsx-ai-factory/nvke
Daily Dose of Data Science | Avi Chawla | Substack12 Hot9 min
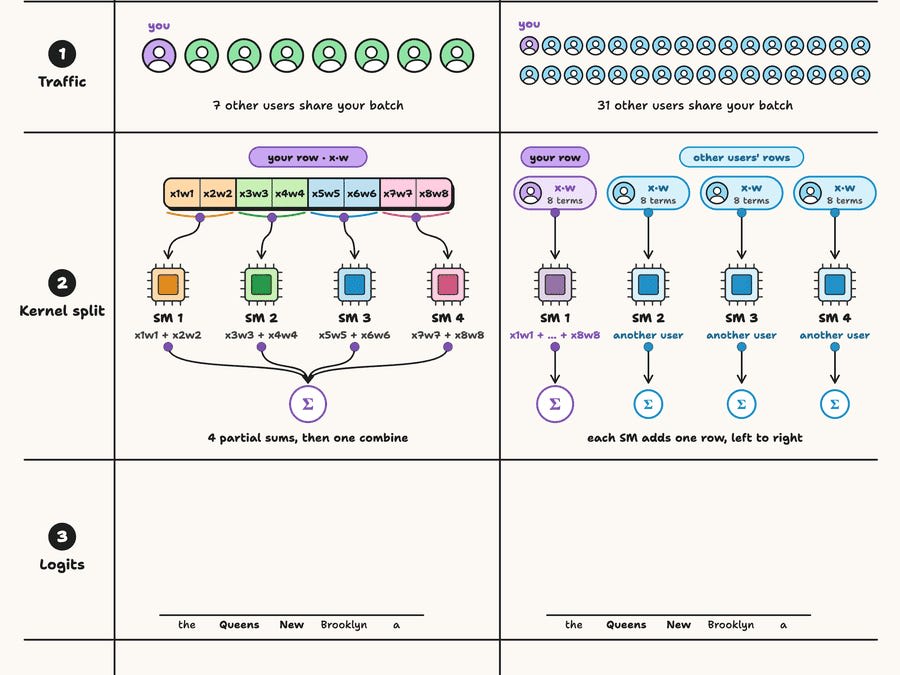
Why Other Requests Change Your LLM’s Output
+ an update on Harness Engineering 2.0.

NVIDIA1 Hot2 min
Vera Delivers the Best of Both Worlds: Highest Throughput and Fastest Agents
As businesses put more agents to work, AI factories need CPUs that can execute those steps quickly and support many agents at once, all within the limits of available power.

XDA Developers1 Hot4 min
I spent $500 to upgrade my aging gaming PC, and it beat buying a new one
A high-end GPU, a modern CPU, and 32GB of RAM

.NET Blog1 Hot3 min
Modernize your .NET apps for Windows Arm64 with GitHub Copilot
The GitHub Copilot upgrade agent now supports migrating .NET applications from Windows x64 or x86 to Windows Arm64. It assesses your projects, flags blockers like architecture-tied build settings and native dependencies without Arm64 binaries, then builds a migration plan. The agent updates code, dependencies, and project configuration, and builds the migrated app for Arm64, running tests when matching hardware or CI runners are available. It focuses on portability and correctness, not Arm64 performance tuning. To start, install GitHub Copilot upgrade, pick the .NET Arm64 migration scenario, and review its plan before letting it make changes.
Comments
Loading comments…