Loading feed…
Phoronix0 Hot0 comments1 min read
CUDA Oxide 0.3 Vastly Improves Rust Support For NVIDIA CUDA Programming
CUDA Oxide 0.3 now works with stable Rust instead of requiring nightly builds. The release uses Rust 1.99.1 and unifies the host runtime with cutile-rs inside the cuda-rust monorepo. It also ships an experimental 'cute-rs' as the CUTLASS CuTe in Rust, which it runs end to end with Qwen3-8B at BF16 plus NVFP4 and Qwen3-TTS, with those models being tested on NVIDIA Blackwell GPUs. The update adds full cuda-gdb DWARF debugging support, in-kernel event tracing, register and spill diagnostics, and performance and compiler optimizations for Blackwell and Hopper GPUs.
Source: https://www.phoronix.com/news/CUDA-Oxide-0.3. 8 Sync News only summarizes and links out; content copyright belongs to the authors and original sources.
8 Sync ecosystem
One account, the whole ecosystem
Read the news here, practice coding, follow structured courses and train for IELTS on our sibling products — all connected through one 8 Sync account.
8syncdev.com
8syncdev.comThe ecosystem home: product overviews, blog and full pricing.
ExploreCourses
course.8syncdev.comLearn along a clear roadmap: videos, auto-graded quizzes, certificates and mentors who ship for a living.
View the roadmapCoding practice
coding.8syncdev.com1,000 DSA problems in Vietnamese, auto-graded across 7 languages — many FREE, right in your browser.
Practice for freeIELTS
ielts.8syncdev.comAI grading for all four IELTS skills with detailed rubric feedback.
Try it freeZUS — AI IDE
zus.8syncdev.comA 22 MB AI IDE for Vietnamese devs.
Download freemind0
mind0.8syncdev.comOrganizational memory for AI agents.
ExploreAcoLeads
home-acoleads.8syncdev.comAI that staffs your Fanpage and qualifies leads for you.
Try itRecommended for you

Hacker News5 Hot6 min
Nibnib: Image compression with extreme decompression speed
Image compression at 4bpp with extreme decompression speed - raphlinus/nibnib

Medium3 Hot39 min
Saving 100TB of RAM with Math. Rebuilding Cloudflare’s Hash Ring from Scratch in Rust
“” is published by Ridwan Alam.

XDA Developers119 Hot4 minAI
I changed one llama.cpp flag, and my 8GB laptop GPU now runs a 35B model faster than I can read
Một lập trình viên đã tìm ra cách chạy model Llama 35B trên laptop GPU chỉ 8GB VRAM với tốc độ đáng kinh ngạc. Nguyên nhân kỹ thuật nằm ở việc chỉnh sửa cờ n_gpu_layers trong llama.cpp, cho phép tận dụng hiệu quả bộ nhớ VRAM thay vì để nó trở thành điểm nghẽn. Hệ quả là model 35B parameters chạy nhanh đến mức người dùng không kịp theo dõi, vượt xa các kỳ vọng ban đầu về giới hạn phần cứng. Điều đáng học hỏi là đôi khi vấn đề không nằm ở cấu hình phần cứng mà ở cách tối ưu hóa phần mềm để khai thác tiềm năng thực sự của hardware.
Bài viết tiết lộ cách tối ưu hóa một cờ trong llama.cpp để chạy mô hình 35B trên GPU 8GB nhanh hơn tốc độ đọc của bạn.

Hacker News25 Hot4 minAI
PaperPilot – Zero-Cloud, Pure-Rust PDF Engine with WASM and MCP
PaperPilot là một AI copilot chạy local cho tài liệu PDF, được phát triển hoàn toàn bằng …
Hacker News15 Hot15 min
Four Months of Zig
A developer reflects on four months of using Zig after returning to it from Rust. She praises Zig's explicit allocator and IO parameters, its build system (adopted by Uber for software written in other languages), comptime, and its lean dependency culture, where her projects have one or two direct dependencies and zero indirect ones versus dozens of indirect dependencies in Rust. Incremental compilation via 'zig build --watch -fincremental' currently only works on x86_64 Linux and macOS. She criticizes poor documentation, missing lifetime checks for stack-allocated buffers, lack of compile-time allocators for JSON parsing, and Zig's bootstrapping process that blocks Debian packaging. She still plans to keep using Zig as her go-to language for most projects.

Hacker News100 Hot36 minAI
Show HN: Spotatui, a Spotify TUI/GUI without web API rate limits
Spotatui là một ứng dụng trình phát nhạc terminal tự viết bằng Rust, kết nối trực tiếp với Spotify mà không cần qua web API, tránh giới hạn rate limits. Công nghệ này sử dụng thư viện librespot và nghe được nhiều nguồn nhạc như Spotify, local files, Subsonic, radio, Qobuz và YouTube trong một giao diện terminal. Người dùng không còn lo về giới hạn API của Spotify mỗi khi muốn phát nhạc. Với việc tự build protocol, Spotatui cung cấp trải nghiệm nghe nhạc mượt mà mà không phụ thuộc vào REST API. Đáng học hỏi ở đây là cách tiếp cận reverse engineering để tự xây dựng client thay vì phụ thuộc vào API chính thức của nền tảng.
Một lập trình viên nên đọc bài này vì Spotatui mang lại trải nghiệm nghe nhạc Spotify trực tiếp trong terminal mà không bị giới hạn API.
Daily Dose of Data Science | Avi Chawla | Substack12 Hot7 minAI
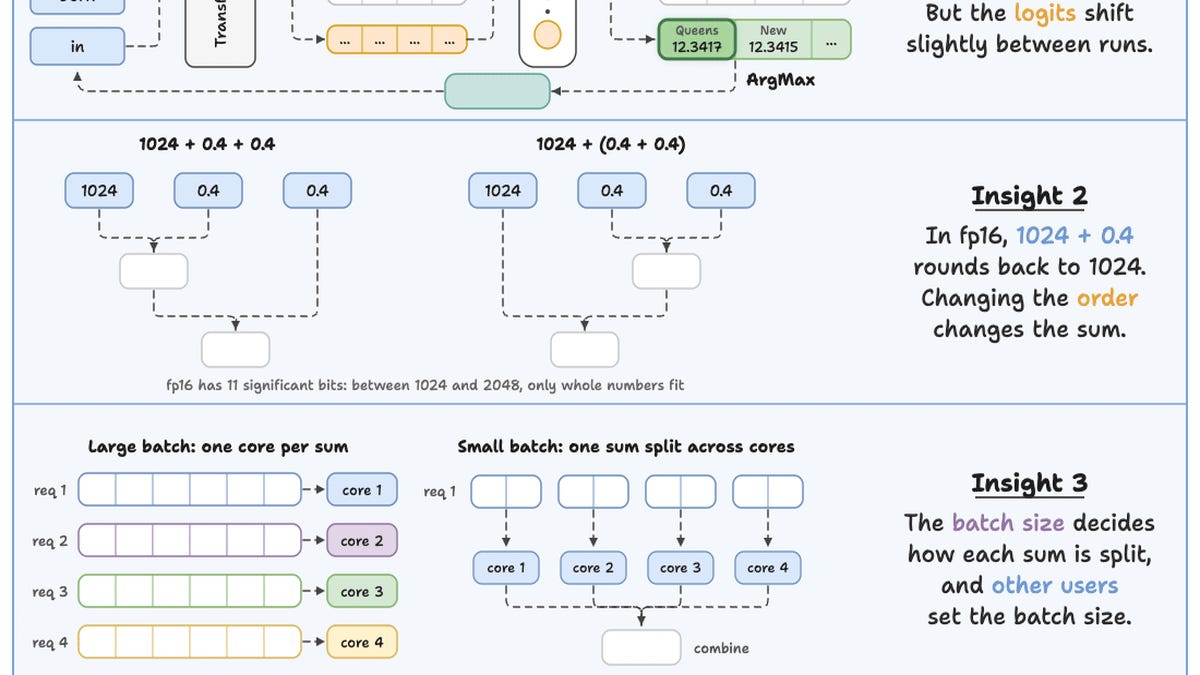
Why Temperature 0 Isn't Deterministic in LLM Inference
Trong quá trình inference của LLM, temperature 0 không hoàn toàn quyết định như nhiều người vẫn nghĩ. Nguyên nhân kỹ thuật nằm ở cách thuật toán softmax hoạt động khi temperature bằng 0, làm cho xác suất của từ với highest score tiến tới 1 nhưng không bao giờ đạt hoàn toàn 1 trong thực tế. Điều này dẫn đến kết quả có vẻ ngẫu nhiên dù xác suất đã được chuẩn hóa, gây ra sự không chắc chắn nhỏ trong kết quả output. Điều đáng học là việc hiểu behavior của temperature trong LLM không đơn giản như tưởng tượng, đòi hỏi hiểu biết sâu về cách hoạt động của softmax và quy trình sampling text generation.
Bạn nên đọc bài này để hiểu cách giải quyết một vấn đề cơ bản nhưng thường bị nhầm lẫn trong việc phân tích và tối ưu hóa mô hình ngôn ngữ lớn, giúp tránh sai lầm trong việc thiết kế và triển khai hệ thống AI.

Medium1 Hot13 min
What If Your Construction Project Had an AI Crew?
What If Your Construction Project Had an AI Crew? Thirteen specialist agents, each with a job, a memory and a reason to follow up. What this means for construction, infrastructure and the products we …
Comments
Loading comments…